Lifecycle
POST /api/v1/jobs returns a job ID and reservation. Poll GET /api/v1/jobs/{id} until the status is succeeded, failed or cancelled; inspect delivered and failed records before downloading.
Use these docs to create Amazon jobs, choose the right input type, poll progress and download structured exports from ParseShelf.
{
  "schema_version": "1.0",
  "status": "succeeded",
  "outcome": "full",
  "has_failures": false,
  "marketplace": "amazon",
  "input_type": "product_url_list",
  "mode": "full_product",
  "delivered_records": 1,
  "records_delivered": 1,
  "records_failed": 0,
  "charged_units": 5,
  "sample": {
    "asin": "B0060OUV5Y",
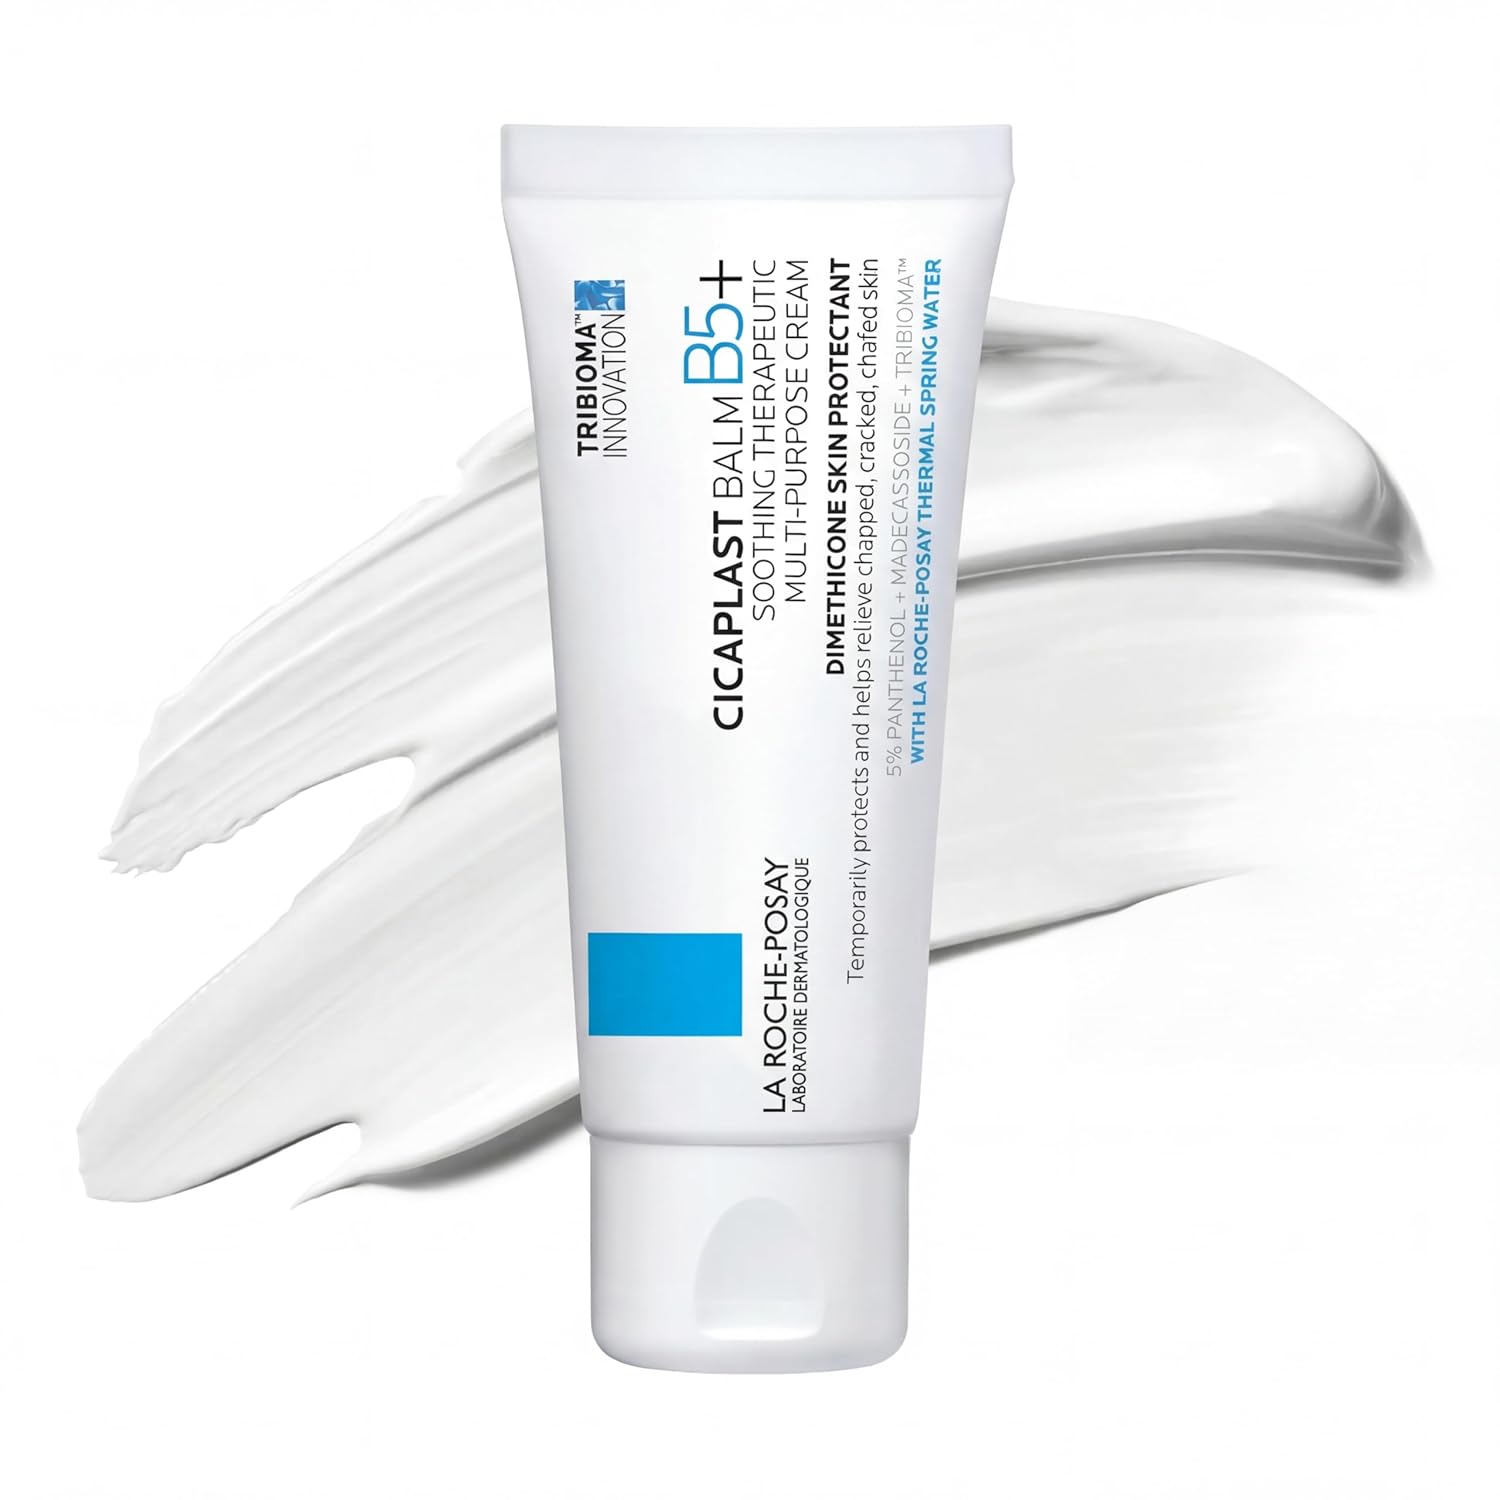
    "title": "La Roche-Posay Cicaplast Balm B5 Cream",
    "brand": "La Roche-Posay",
    "price": 18.99,
    "currency": "USD",
    "stock_status": "in_stock",
    "stock_text": "In Stock",
    "product_url": "https://www.amazon.com/dp/B0060OUV5Y",
    "rating": 4.7,
    "reviews_count": 20743
  },
  "exports": {
    "jsonl": "/api/v1/jobs/{job_id}/download/jsonl",
    "csv": "/api/v1/jobs/{job_id}/download/csv",
    "xlsx": "/api/v1/jobs/{job_id}/download/xlsx",
    "md": "/api/v1/jobs/{job_id}/download/md"
  }
}
# Amazon product sample

| ASIN | Product | Price (USD) |
| --- | --- | --- |
| B0060OUV5Y | La Roche-Posay Cicaplast Balm B5 Cream | 18.99 |

Illustrative row. Run a live preview for current data.
curl -X POST https://parseshelf.com/api/v1/jobs \
  -H 'Authorization: Bearer $PARSESHELF_KEY' \
  -H 'Content-Type: application/json' \
  -d '{"marketplace":"amazon","input_type":"product_url_list","input_value":"https://www.amazon.com/dp/B0060OUV5Y","mode":"full_product","target_count":20}'
Build the integration around explicit states instead of treating a successful HTTP response as complete data.
POST /api/v1/jobs returns a job ID and reservation. Poll GET /api/v1/jobs/{id} until the status is succeeded, failed or cancelled; inspect delivered and failed records before downloading.
A job can deliver listing-level fallback rows when a richer product page did not render. Use the quality summary to decide whether the output is sufficient; if you need richer fields, rerun the selected ASINs in full_product mode.
Handle 400 validation, 401/403 authentication or access, 404 missing jobs/exports, 429 capacity limits and 5xx provider failures. Use the response message as operator context and retry only transient capacity/provider failures.
The public job-create request accepts an optional Idempotency-Key. Reusing the same key with the same request returns the original job without reserving units twice; reusing it for different input returns 409. Persist the returned job ID alongside your request key.
The public v1 contract is polling-based and does not claim webhook delivery. Use the paginated /api/v1/jobs/{job_id}/rows endpoint when you need canonical records before downloading; store the job ID, source URL, mode and run date for reconciliation.
Start with the public contract; request organization-specific documents when a pilot is approved.
API keys are shown once, stored hashed, scoped to the owning workspace and revocable. Keep them in a secret manager and never in a browser URL.
Review acceptable use →The v1 row contract names asin, product_url, stock_status and stock_text; delivered, failed and partial rows remain visible in job metadata and exports.
Compare the free sample, reviewed sample, pilot and self-serve plans only after confirming your input and field coverage.
Compare plans →For a procurement review, include your marketplace, expected rows, cadence, retention needs and required export fields.
Request procurement packetOpen a screenshot to inspect the actual path from input to output and observed intelligence.
A ParseShelf job starts with a marketplace, input type, input value, mode and target count. The same contract works for Amazon search URLs, category URLs, product URLs and ASIN lists, so a developer can switch sources without rewriting downstream export logic.
The dashboard and API share the same job lifecycle. Operators can create and inspect jobs in the web product while engineers automate recurring runs with API keys.
The v1 contract uses asin, product_url, stock_status and stock_text as canonical Amazon fields, plus title, brand, price, currency, rating, reviews_count, category_path and images. Existing exports may include product_id as a deprecated compatibility alias for asin; new integrations should use asin.
Each export format is generated from the same normalized rows. JSONL is best for pipelines, CSV and XLSX are best for analysts, and Markdown is useful for internal reports.
Use the rows endpoint when a client needs paginated canonical records before downloading a file. It accepts search, sort, quality and page parameters and returns the same ProductRow shape as the exports.
If a completed full_product job contains listing-fallback rows, POST to the repair endpoint to queue an additive retry. The repair response has its own state and reservation; clients should poll the parent job and keep the original row quality visible.
Start with the API overview if you need the complete endpoint map. Use the Python or JavaScript quickstart when you are wiring ParseShelf into a backend. Use the Google Sheets and Postman guides when the first user is an operator or analyst.
For SEO and research workflows, pair these docs with the public sample dataset and benchmark page so buyers can evaluate the data shape before signing up.
Start with one small input and compare the delivered fields with the report, catalog or pipeline you actually need.
Keep the job ID, source URL, mode and run date with downstream exports so operators and developers can audit the same result.